

I ship AI-written code into a repo that senior engineers review. I can read it — I couldn’t have written it.
That raises a fair question: how do I take responsibility for work I couldn’t have written? I think more people are going to face that question as AI-assisted development becomes part of their work.
To be exact about where I sit: HTML and CSS, I’m a Jedi. TypeScript and full-stack development are where I need engineering review. I can follow the logic in the code that comes back and I can tell you what it should do. I can’t produce it on my own. So the work is describing what I want, pointing at the existing codebase as the guide, and iterating, then checking the result with tools and the people who will maintain it.
The good material on AI-assisted development, Simon Willison’s ongoing writing and the Fowler-adjacent work on verification speed, is written for a developer who can review the output. That’s the right audience and I learn from it constantly. I also want to address a different reader: the person directing the work who cannot personally distinguish a correct claim from a confident wrong one, while the reviewers downstream absolutely can.
That’s me. Possibly it’s you.
The problem isn’t the code
When I actually measured it, the result surprised me.
I spent two days watching four models work real defects in a production codebase and graded every result. I expected the near-misses to be bad reasoning about code. Almost none of the failures I recorded were. Two days with four models isn’t a verdict on every model. It changed where I put my attention.
What broke in the examples below was the instrument, the check the model used to verify its own claim:
- A file count that included
.gitinternals. Came back as a plausible number. - A process check where the
grepmatched its own pattern in the process list. - A search through
.cssfiles for a style the framework inlines into JS chunks. Zero hits, reported as “the fix isn’t in the artifact.” - A conclusion about which session did what, drawn from a log written by a hook rather than the transcript.
Every single one arrived as a finding with a number attached. None arrived as an error.
And it isn’t a model problem I can wait out, because it happens to me on my own work. I was exploring a layout idea in code recently, a small thing, a column that needed to hold its width through a resize. I asked for the fix, got it, and asked for proof. Back came a tidy report: the offending style found, removed, build clean. I believed it. Then I dragged the window and watched the column ratchet wider on every pull, exactly as before. The search had looked in the stylesheet. The framework had put that style somewhere else entirely, and the report had never been capable of finding it.
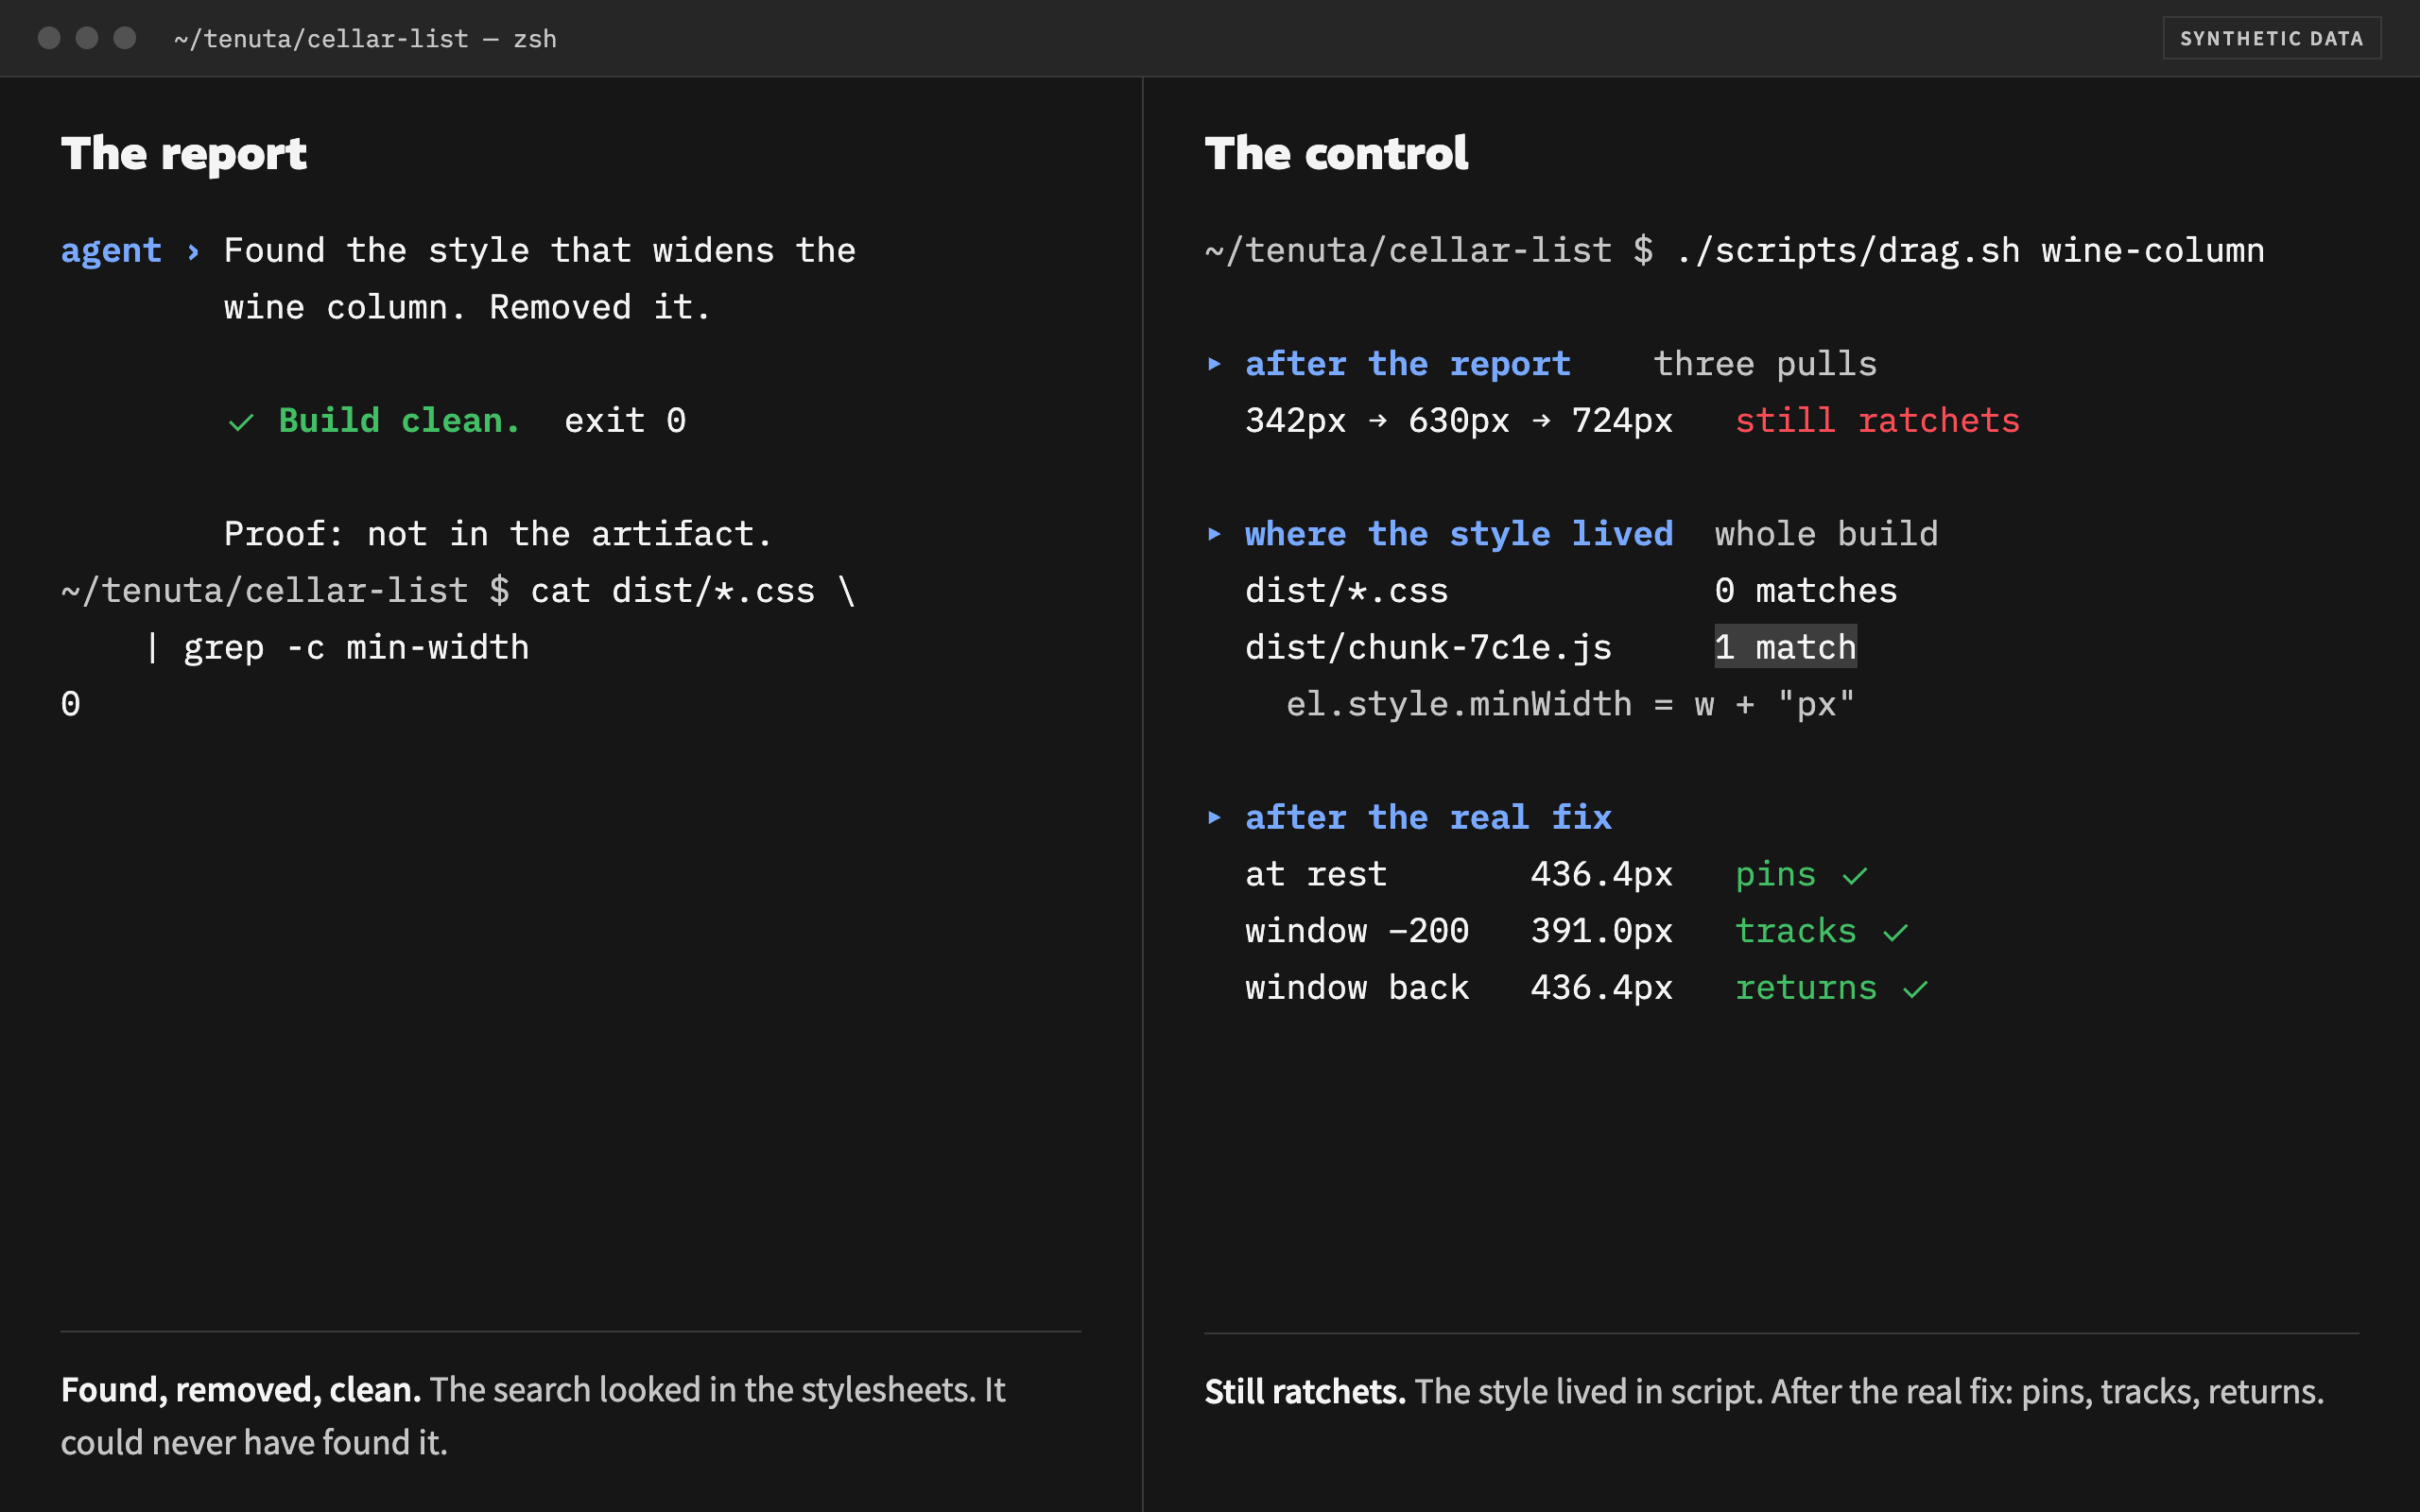
The instrument passed. The thing was still broken — and only using it caught it.
The one tell that works
Every failure above called for the same question: what did you check that against?
In these examples, testing the check against a case known present and a case known absent exposed the error. Without a stated control, I couldn’t tell whether the number was reliable.
So that’s the tell. Not confidence, not detail, not how good the explanation sounds. A claim with no stated control.
I can’t audit a diff. I can absolutely ask what the control was, and I can tell when there wasn’t one.
Four gates
I’m not the verifier. I route verification, to tools and to people who can actually do it, and I make sure nothing reaches a reviewer without evidence attached.
- Sort claims by blast radius. Four claims can send the next person down the wrong path, so I check them closely: tests pass · this is the only place it occurs · this is the root cause · verified in the browser. For the rest, I ask what happens if this is wrong.
- Dangerous claims carry a command and its output, or they’re labeled unproven. A command and an exit code are readable without knowing the framework. “I checked” isn’t evidence.
EXIT:0tells me the command completed successfully. It only supports the larger claim if the command tested the right thing. - Demand the negative case. “It works” is half a result. The other half is the before-state, or the case where it fails. Pre-fix the column ratchets 342 → 630 → 724px; post-fix it pins at 436.4px, tracks a real resize, and returns. A non-programmer can check that shape. I still need to confirm that the observation comes from the right element and state.
- Someone who isn’t the implementer checks first. I aim to make that an independent check before formal review. In the failures I recorded, remembering to trigger the check was often the gap.
The part that’s actually leverage
I can’t verify the code. What I can do is install the discipline, and I’ve used that discipline across models, including ones new to the codebase.
What I mean by discipline is this: an environment that catches specific mistakes before they reach a reviewer, built out of gates and guards that fire whether or not anyone remembers to check. A stop-gate blocked a model’s first “done” and turned a read-through into real browser-plus-test execution. A pre-execution guard caught a masked exit code and taught the shell-correct way to read one. A post-execution reminder produced consistent artifact-checking instead of trusting a green build message.
Those checks live in the workflow instead of relying only on a prompt. And it’s available to someone who can’t write the diff, which is why I think it’s the highest-leverage thing in this whole practice.
What I don’t know
Whether the strong models are intrinsically careful or just compliant with that coaching. I’ve watched both explanations fit the data.
It matters, because those imply opposite investments. If they’re careful, the scaffolding is a cost I can shed. If they’re compliant, the scaffolding is the product and I should build more of it.
I don’t have that answer yet. I’m designing a comparison that could help separate the two explanations.
Looking credible in front of people who can read the code
Credibility here is the relationship you have with the team, and I’m not afraid to come to the table. I’m not pretending to be a developer and never will. But I know enough that it isn’t over my head. I can participate, and I can shape the logic by thinking pragmatically about what the user experience needs to do.
Some habits, learned the hard way:
- Be clear about what you bring. Bring your own strengths, name the ones you don’t have, and let the people who can read the code read it.
- Explain the logic and the use case, not the code. If I can walk a developer through the reasoning I used to get somewhere, and give them the situation it’s for, we’re speaking the same language even though I can’t write theirs.
- Hand over the spiked branch as the prototype. The branch makes the proposed experience concrete, so the team can use it to discuss behavior and remaining questions. I label it as a prototype and work with engineering on what to keep, rebuild, or discard.
- If I can’t communicate what needs to get done, I need to rethink how I’m explaining it. When I can’t communicate what needs to get done, I go back and rethink how I’m explaining it and what the logic actually is.
- Share the evidence line, not the conclusion. “Fixed the sticky offset” invites interrogation. “Removed the two inline writes that clobber it, build exit 0, declaration confirmed in the built chunk, before/after computed values attached” gives the reviewer something concrete to inspect.
- Say what isn’t proven, first. Naming the gap yourself converts a reviewer’s catch into your disclosure. It gives the reviewer an honest starting point.
- Know what your reviewer actually enforces. Read the team’s conventions and previous review feedback, so avoidable issues don’t consume the next review.
- Never carry a claim you can’t source. If the honest answer to “how do you know?” is “the model said so,” it isn’t ready to share.
That last one is the whole discipline, really. Catching a mistake before handoff is usually cheaper than asking the next person to discover it. Credibility comes from making the work inspectable and responding well when someone finds a gap.
Two things I’ve left out on purpose
Most of what’s above is me working with AI and the developers not. That asymmetry is the real story. If they worked with it too, or set up the context for me so a spike came back closer to what they’d want, I’d be handing over what they expect instead of what I could reach. I don’t know how to write that piece yet, but it’s coming.
And development is only the first channel. Without development, we don’t see anything. But QA needs to test the thing without reading the code, product needs to know what’s proven, and leadership needs to understand what it’s doing at all. It takes a village, and that’s a piece of its own.