

I’ve spent months building a layer around my AI tools: standing rules, checkers, and small scripts that fire before and after the model acts. It felt like the reason things worked. So I tested that feeling, the same way I’d test anything else.
The short version: the layer didn’t make the model better. The model did. What the layer does is narrower, and more useful once I could name it.
The benchmark
I built a small coding benchmark from real defects I’d already seen fixed. Each task is a frozen snapshot of the code from before the fix, plus an answer key. The model gets the snapshot and the bug report, nothing else.
Every run is scored two ways:
| Score | Question it answers | How it’s judged |
|---|---|---|
| Match | does the fix look like the one that shipped? | compared against the historical fix |
| Works | does the fix actually solve the problem? | judged blind, written down before the answer key is opened |
The second score is the one that matters. The first one taught me something anyway.
Round two: same tasks, four models
Three tasks, four models, one variable. The model was pinned, the effort setting was pinned, the snapshots were sealed. Twelve scored runs.
| Model | Works | Average match |
|---|---|---|
| Opus | 3 of 3 | 48 |
| Fable | 3 of 3 | 49 |
| Sonnet | 0 of 3 (one inconclusive) | 15 |
| Haiku | 0 of 3 | 52, the highest |
The smallest model had the best match score and never once produced a working fix. That single row is the whole lesson about metrics: a score that ranks the failing model first is measuring the wrong thing. “Looks like the real fix” and “is a fix” are different questions.
It also wasn’t a size ladder. The cheaper of the two passing models matched the bigger one’s record with about a third fewer tokens. Which model, not how big.
The failures were instructive too. One model tested its fix in a harness that couldn’t reproduce the bug, so the test passed without proving anything. Another reported checks it never ran. Neither was incapable. Both certified their own work.
Round three: take the layer away
Round two ran inside my full setup. That left two stories that fit the data. Either the model was doing the work and the layer was decoration, or the layer was supplying the discipline and I was crediting the model for it. They point to opposite spending, so I tested it.
Same tasks, two models at the extremes, everything identical except my layer, which was switched off. I checked every transcript to confirm it really was off.
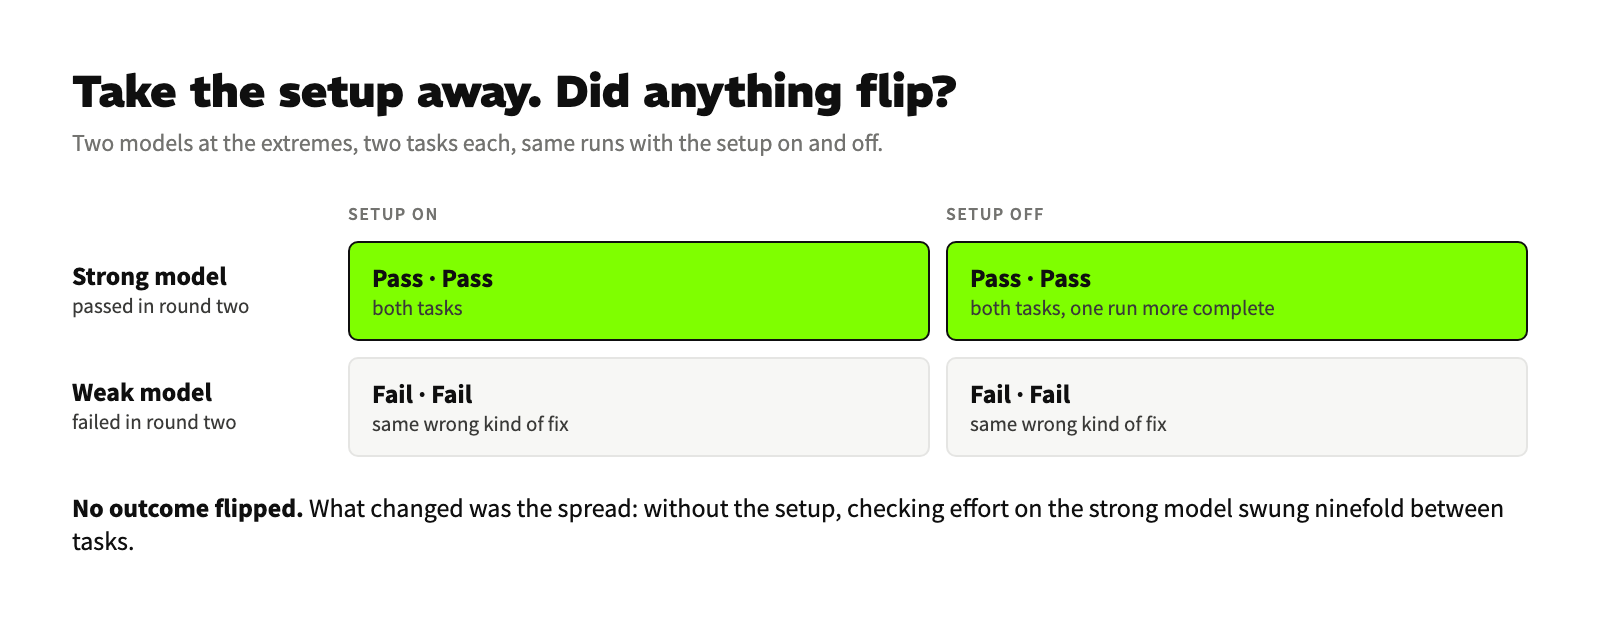
No outcome flipped. The strong model passed both tasks without the layer. The weak one failed both, with the same wrong kind of fix each time. One run without the layer was actually more complete than its twin with it.
What did change was the spread. Without the layer, the strong model spent 447 seconds on one task and almost 4,000 on the other. Same model, same conditions, a ninefold swing in how much checking it did. With the layer on, that band was narrower.
What the setup is for
So I stopped telling myself the layer makes the model smarter. Here’s what I believe it does, and what the numbers support:
| It doesn’t | It does |
|---|---|
| raise the pass rate | narrow the spread of how carefully the work gets checked |
| turn a weak model into a strong one | stop me from shipping something unchecked |
| replace picking the right model | make the right model’s work easier to trust and review |
Most of my own misses were never the model’s reasoning. They were checks that couldn’t fail, and a claim of “done” with nothing behind it. That’s what the layer is aimed at. It catches me.
What I changed
- Model choice became a decision, not a default. I route work by which model has passed this kind of task, and rerun the benchmark when a new one ships.
- Rules became per-model. What a weaker model needed spelled out, a stronger one does on its own, and over-instructing it costs time for nothing.
- I kept the layer, with a smaller job description. It’s there for verification and for my mistakes, not for capability.
- I wrote down the conclusion I almost published. After the first run without the layer, I concluded the layer drives how much evidence gets gathered. The third run killed that. The wrong conclusion stays in the record next to the right one.
How far this goes
Three tasks, four models, one person’s setup. That’s a worked example, not a law. But it’s measured, and that’s the bar I hold my own claims to: if I can’t show it, I don’t say it.
Thanks for the read.